Java 26 shipped a one-line feature most developers walked right past. It hides in the HttpClient, in a class nobody reads for fun: HttpRequest.BodyPublishers. The method is ofFileChannel, and it quietly solves a problem I have hand-rolled at least three times in my career.
The problem: uploading one big file as several parts, in parallel, without reading the whole thing into memory. Think S3-style multipart uploads, resumable backups, or any API that takes a file in ranges. Until now, doing this from the standard library meant ugly workarounds. With ofFileChannel, it's a single channel and a loop.
Let me show you the method, why it matters, and the exact code to upload file slices in parallel.
What is ofFileChannel in Java's HttpClient?
ofFileChannel is a BodyPublisher factory added in JDK 26 that streams a specific byte range of a file as the request body. Here is the signature straight from the Java 26 docs:
public static HttpRequest.BodyPublisher ofFileChannel(
FileChannel channel, long offset, long length) throws IOExceptionYou hand it an open FileChannel, a starting offset, and a length in bytes. The returned publisher sends exactly those length bytes, read straight from the channel as the body streams out. Nothing gets buffered into a byte[] first.
Two sentences in the Javadoc do all the heavy lifting. The method "do[es] not modify the channel's position, and do[es] not close the channel." That sounds boring. It's the most important detail in the whole API, and I'll explain why in a second.
Why was uploading file slices in parallel so awkward before?
Before JDK 26, every option for uploading a file region had a real downside. The standard library gave you three body publishers for files, and none of them fit cleanly.
BodyPublishers.ofFile(path) uploads the whole file as one body. No offset, no length, no slicing. If your API wants the file in 16 MiB parts, ofFile can't help.
BodyPublishers.ofByteArray(slice) works for a region, but you have to read that region into a byte[] first. Upload a 4 GiB file in eight parts and you're holding up to 512 MiB of slices in the heap at once. On a busy service that's how you earn a 3 a.m. page.
BodyPublishers.ofInputStream(supplier) streams without buffering, but it's built around a single InputStream and a Supplier for retries. Pointing several concurrent streams at different regions of the same file means juggling positions and seeks by hand, and one shared stream is not safe to read from many threads at once.
So people did what people do. They wrote a custom BodyPublisher over a RandomAccessFile, got the Flow.Subscriber back-pressure subtly wrong, and shipped it anyway. I've reviewed that code. I've written that code.
ofFileChannel removes the reason to write any of that. It streams a region with zero buffering, and because it leaves the channel position alone, you can point many publishers at one channel safely.
How do you upload a single file region with ofFileChannel?
Start with the simple case: send one byte range and ignore parallelism. This is the building block for everything else.
import java.io.IOException;
import java.net.URI;
import java.net.http.HttpClient;
import java.net.http.HttpRequest;
import java.net.http.HttpRequest.BodyPublishers;
import java.net.http.HttpResponse;
import java.nio.channels.FileChannel;
import java.nio.file.Path;
import java.nio.file.StandardOpenOption;

int uploadRegion(Path file, long offset, long length, URI target)
        throws IOException, InterruptedException {

    HttpClient client = HttpClient.newHttpClient();
    try (FileChannel channel = FileChannel.open(file, StandardOpenOption.READ)) {
        HttpRequest request = HttpRequest.newBuilder(target)
                .header("Content-Type", "application/octet-stream")
                .PUT(BodyPublishers.ofFileChannel(channel, offset, length))
                .build();

        HttpResponse<String> response =
                client.send(request, HttpResponse.BodyHandlers.ofString());
        return response.statusCode();
    }
}That's the entire dance. Open the channel read-only, build a PUT with the range, send it. The try-with-resources closes the channel, which is correct here because the synchronous send has already finished by the time we leave the block. Keep that timing in mind. It's about to matter a lot.
How do you upload file slices in parallel from one FileChannel?
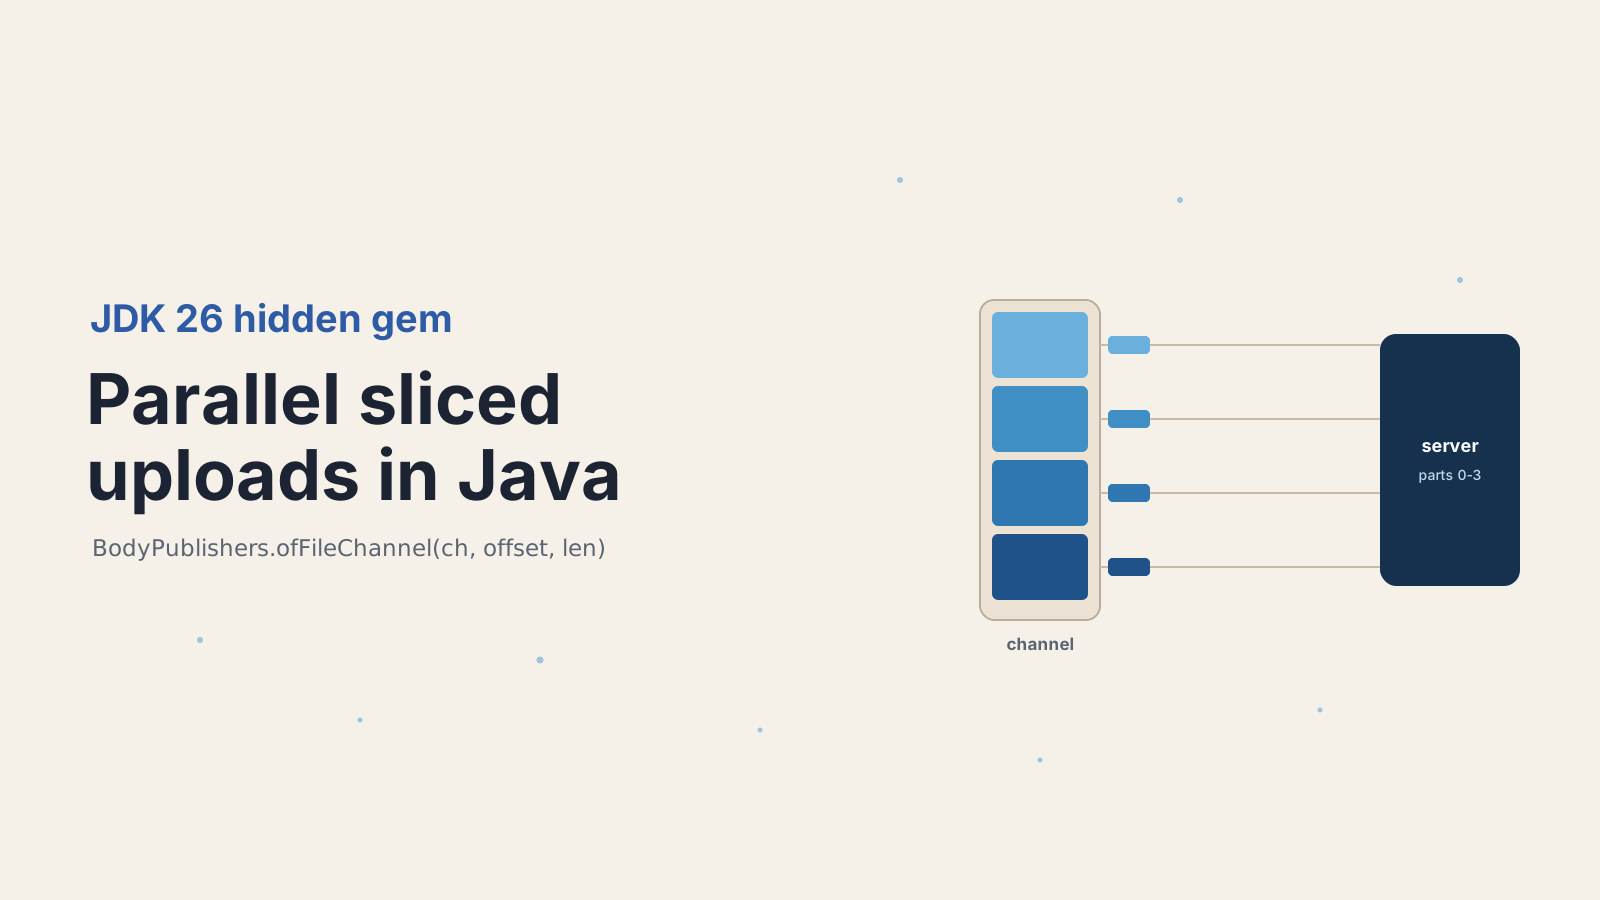
Open one FileChannel, build one ofFileChannel publisher per slice, and fire every request with sendAsync. The channel is shared, the ranges don't overlap, and the position never moves, so the reads don't step on each other.
import java.io.IOException;
import java.net.URI;
import java.net.http.HttpClient;
import java.net.http.HttpRequest;
import java.net.http.HttpRequest.BodyPublishers;
import java.net.http.HttpResponse;
import java.nio.channels.FileChannel;
import java.nio.file.Path;
import java.nio.file.StandardOpenOption;
import java.util.ArrayList;
import java.util.List;
import java.util.concurrent.CompletableFuture;

public final class SlicedUploader {

    private static final long SLICE = 16L * 1024 * 1024; // 16 MiB per slice

    public void upload(Path file, String partUrl) throws IOException {
        HttpClient client = HttpClient.newHttpClient();

        try (FileChannel channel = FileChannel.open(file, StandardOpenOption.READ)) {
            long total = channel.size();
            long sliceCount = Math.ceilDiv(total, SLICE); // Math.ceilDiv is Java 18+
            List<CompletableFuture<HttpResponse<String>>> uploads = new ArrayList<>();

            for (long i = 0; i < sliceCount; i++) {
                long offset = i * SLICE;
                long length = Math.min(SLICE, total - offset); // last slice is smaller
                HttpRequest request = HttpRequest.newBuilder(URI.create(partUrl + "/" + i))
                        .header("Content-Type", "application/octet-stream")
                        .header("Content-Range",
                                "bytes %d-%d/%d".formatted(offset, offset + length - 1, total))
                        .PUT(BodyPublishers.ofFileChannel(channel, offset, length))
                        .build();

                uploads.add(client.sendAsync(request, HttpResponse.BodyHandlers.ofString()));
            }

            // The channel must stay open until every slice finishes.
            CompletableFuture.allOf(uploads.toArray(CompletableFuture[]::new)).join();
        }
    }
}Walk through what makes this safe. Each iteration calls ofFileChannel(channel, offset, length) with a different, non-overlapping range. Since the publisher reads positionally and never advances the channel's own position, four in-flight reads at offsets 0, 16M, 32M, and 48M see exactly their own bytes. No locks, no seeks, no copies.
The Content-Range header is mine, not the JDK's. ofFileChannel handles the client side of streaming bytes. Telling the server which bytes these are is your job, and Content-Range is the usual way to do it.
This is the pattern the Javadoc itself recommends. It spells out the intended use: "create a single instance of FileChannel and then send multiple concurrent HttpRequests, each of which uses a new ofFileChannel BodyPublisher created from the same channel with a different, typically non-overlapping, range." The standard library is telling you to slice files in parallel. Take it up on the offer.
If you'd rather use the blocking send per slice instead of sendAsync, run each one on its own virtual thread. The HttpClient is happy with thousands of concurrent blocking sends when they're cheap. I wrote up that model in my guide to virtual threads in Java, and it pairs perfectly with this.
How does the upload server reassemble the slices?
The server stitches the parts back together using whatever scheme you put on the wire, because ofFileChannel is a client-side streaming tool and nothing more. It moves bytes. It has no opinion about your upload protocol.
In practice you'll match one of three patterns. With an S3-style multipart API, each request is an UploadPart call carrying a part number, and the service assembles them on CompleteMultipartUpload. With your own endpoint, a Content-Range header (like the code above) tells the server where each chunk lands in the final file. With a multipart/form-data form, each slice is a named part and the server concatenates in order.
Pick one and own both ends. The common mistake is assuming the JDK does the reassembly. It doesn't. It hands the server your bytes with whatever headers you set, and stops there.
What are the pitfalls of ofFileChannel sliced uploads?
Most of the traps come down to channel lifetime and range math. None are hard once you've seen them once, so here's the list I keep in my head.
Keep the channel open until every request finishes. This is the big one. With sendAsync, the requests outlive the loop, so closing the channel too early is a real risk. That's why CompletableFuture.allOf(...).join() sits inside the try-with-resources in the code above. Close the channel before the async sends drain and you'll get failures from a closed channel.
Get the range math right. ofFileChannel throws IndexOutOfBoundsException if offset plus length runs past the end of the file. The last slice is almost always smaller than the rest, so clamp it with Math.min(SLICE, total - offset). Off-by-one here is the difference between a clean upload and a truncated file.
Don't mutate the file while it's uploading. The publisher reads live bytes from the channel as the body streams. If another thread truncates or rewrites the file mid-upload, the bytes on the wire change with it. Upload from an immutable or snapshotted file.
It plays nicely with retries. Unlike ofInputStream, which needs a Supplier because a stream can't be re-read, an ofFileChannel publisher can re-read its range on demand. That means redirects and HttpClient retries just work, as long as the channel is still open.
Mind your concurrency width. Firing 500 slices at once won't help if the server throttles you or your uplink saturates. Tune the slice size and cap in-flight requests. This is the same JDK 26 HttpClient that also brought HTTP/3 support, and HTTP/3's stream multiplexing is a natural fit for many small parallel parts.
Should you use ofFileChannel for big uploads today?
If you're on JDK 26 and you upload large files, yes, delete your custom file-range publisher and use this instead. It's less code, it's in the standard library, and it was designed by the people who own the HttpClient. That combination beats anything you or I would maintain by hand.
The part I keep coming back to is how small the surface is. One method, three parameters, two guarantees about the channel. That's the entire feature. And yet it turns "write a back-pressure-correct streaming uploader" into "open a channel and loop." The best standard-library additions are the ones that make a whole category of custom code obsolete. This is one of them, and almost nobody noticed it ship.
For the full contract, read the BodyPublishers Javadoc for Java 26 and the Inside Java write-up on the JDK 26 HTTP Client.
Keep Reading
- Java 26 HTTP/3 in the HttpClient: A Complete Developer Guide. The other big HttpClient change in the same release, and a great match for many small parallel uploads.
- Mastering Virtual Threads in Java 25. Run each blocking slice upload on its own virtual thread instead of juggling CompletableFutures.
- Modern Java Development: Java 21+ Features and Spring Boot Best Practices. Where features like this fit into a current production Java stack.